Erfan Miahi
Research Scientist · LLM Post-training & RL
About The longer version.
I'm a research scientist at Pluralis, working on decentralized RL post-training, where the rollouts come from machines spread across the internet instead of one datacenter. In July 2026 we post-trained an 8B mixture-of-experts model with 14 Macs in four countries generating rollouts and one B200 training it. Held-out pass@1 on PaperSearchQA went from 29% to 63%.
Before Pluralis I was at Covenant AI, where I helped build Covenant-72B, a 72B LLM from the largest collaborative, globally distributed pre-training run at its release in March 2026, and Grail, an open RL post-training system for LLM reasoning. There I also wrote PULSE, which cuts weight-sync traffic in distributed RL by over 100×. It was accepted at NeurIPS 2026, and Fireworks cites it in their write-up of the infrastructure behind Cursor's Composer 2 RL run.
Before that I was the founding ML research engineer at DeepR Analytics, a Toronto proprietary-trading firm, where I built its RL trading pipeline. I did my M.Sc. at the University of Alberta's RLAI Lab (Richard Sutton's lab), supervised by Martha White and Marlos C. Machado, and worked with Google DeepMind on how neural network representations behave in RL.
Outside work I skydive (60 jumps so far), fly in wind tunnels, do parkour and run long distances. I keep going back to Nietzsche's philosophy and Jung's analytical psychology.
- 294
- Citations, Nov 2026
- 11
- Papers, 3 as first author
- >100×
- Less weight-sync traffic with PULSE
- 29→63%
- PaperSearchQA pass@1, 14-Mac run
- 72B
- Parameters in Covenant-72B
- 10+
- Mentees since 2017
Research Publications & preprints.
NeurIPS EMNLP EACL AIJ MLJ TMLR IEEE T-Cyb 294 citations on Google Scholar, November 2026.
Selected
-
Understanding and Exploiting Weight Update Sparsity for Communication-Efficient Distributed RL
Erfan Miahi, Eugene Belilovsky
About 99% of per-step weight updates are invisible after the BF16 cast. PULSE uses that to cut weight-sync traffic by over 100× with bit-identical weights. Cited by Fireworks.
NeurIPSaccepted -
Covenant-72B: Pre-Training a 72B LLM with Trustless Peers Over-the-Internet
Joel Lidin, Amir Sarfi, Erfan Miahi, Quentin Anthony, Shivam Chauhan, Evangelos Pappas, Benjamin Thérien, Eugene Belilovsky, Samuel Dare
A 72B-parameter LLM from the largest collaborative, globally distributed pre-training run at its release in March 2026 (~1.1T tokens), open to permissionless peers.
arXivpreprint -
Investigating the Properties of Neural Network Representations in Reinforcement Learning
Han Wang, Erfan Miahi, Martha White, Marlos C. Machado, Zaheer Abbas, Raksha Kumaraswamy, Vincent Liu, Adam White
Joint work with Google DeepMind, published in Artificial Intelligence (AIJ).
AIJjournal
All publications
-
How Reliable are Confidence Estimators for Large Reasoning Models? A Systematic Benchmark on High-Stakes Domains
Reza Khanmohammadi, Erfan Miahi, Simerjot Kaur, Charese H. Smiley, Ivan Brugere, Kundan Thind, Mohammad M. Ghassemi
European Chapter of the ACL
EACLmain -
Grounded or Guessing? LVLM Confidence Estimation via Blind-Image Contrastive Ranking
Reza Khanmohammadi, Erfan Miahi, Simerjot Kaur, Charese H. Smiley, Ivan Brugere, Kundan Thind, Mohammad M. Ghassemi
Confidence estimation for vision-language models
arXivpreprint -
Calibrating LLM Confidence by Probing Perturbed Representation Stability
Reza Khanmohammadi, Erfan Miahi, Mehrsa Mardikoraem, Simerjot Kaur, Ivan Brugere, Charese H. Smiley, Kundan Thind, Mohammad M. Ghassemi
Empirical Methods in Natural Language Processing
EMNLPmain -
GVFs in the Real World: Making Predictions Online for Water Treatment
Muhammad K. Janjua, Haseeb Shah, Martha White, Erfan Miahi, Marlos C. Machado, Adam White
Machine Learning (MLJ)
MLJjournal -
ResMax: An Alternative Soft-Greedy Operator for Reinforcement Learning
Erfan Miahi, Revan MacQueen, Alex Ayoub, Abbas Masoumzadeh, Martha White
First author Transactions on Machine Learning Research
TMLRjournal -
Genetic Neural Architecture Search for Automatic Assessment of Human Sperm Images
Erfan Miahi, Seyed Abolghasem Mirroshandel, Alexis Nasr
First author NAS for medical imaging
Expert Syst. Appl.journal -
Scalable Transfer Evolutionary Optimization: Coping with Big Task Instances
Mojtaba Shakeri, Erfan Miahi, Abhishek Gupta, Yew-Soon Ong
NTU × A*STAR collaboration
IEEE T-Cybjournal -
Effect of Deep Transfer and Multi-task Learning on Sperm Abnormality Detection
Amir Abbasi, Erfan Miahi, Seyed Abolghasem Mirroshandel
Most-cited paper Computers in Biology and Medicine
Comput. Biol. Med.journal
Work Projects in the open.
stoa
RL post-training with Apple-silicon Macs as the rollout fleet. The Macs generate rollouts in int8 with MLX, a GPU trains, and weight deltas sync through Cloudflare R2. Our July 2026 run used 14 Macs in four countries.
Covenant-72B
A 72B LLM pre-trained on ~1.1T tokens by permissionless peers over the open internet, in the largest collaborative, globally distributed pre-training run at its release. I helped build it.
Grail
Geo-distributed, incentivized RL post-training for LLM reasoning, where untrusted nodes generate rollouts that are verified before training. Covenant AI's open research stack.
q Evaluation Harness
The first open-source evaluation framework for LLMs on q/kdb+, built with KX. At launch in August 2025 the best model, Grok 4, solved 43.4% of q-HumanEval on the first attempt, against 96.2% for top models on Python's HumanEval.
Draw Your Circuit
A Meta Quest 3 app that turns a hand-drawn circuit sketch into a schematic.
Deep-RL-CS285-Pytorch
PyTorch solutions to Berkeley's CS285 deep RL assignments, my most-starred repo (140+ stars).
Writing Dispatches from the deep air.
Technical posts and essays.
RL Post-Training on Macs
Multi-turn RL of an 8B mixture-of-experts model with 14 Macs in four countries generating rollouts and one B200 training it. Held-out pass@1 on PaperSearchQA went from 29% to 63%.
The Act of Creation
On moving from passive absorption to active curation, and finding the self through creation.
Introducing q Evaluation Harness
The first open-source evaluation framework for LLMs on q/kdb+. At launch the best model, Grok 4, solved 43.4% of q-HumanEval on the first attempt, against 96.2% for top models on Python's HumanEval.
Reading Books at depth altitude.
Books I keep going back to.
The secret for harvesting from existence the greatest fruitfulness and the greatest enjoyment is: to live dangerously.
Mentorship Mentoring since 2017.
I've mentored 10+ students since 2017, in calls every two to four weeks. We mostly work on their life philosophy and how they take on problems in general, with AI research, engineering and entrepreneurship on the side. The calls are a collaboration. Instead of telling them exactly what to do, I give a second opinion on their thought process and approach.
Email me with “Mentorship Program” in the subject line.
- 01
You're ambitious and driven.
- 02
You want to work on your life philosophy and how you take on problems, not just the technical side.
- 03
You'd rather be told the truth than something comfortable.
Off-desk When I surface land.
Skydiving, wind tunnels, parkour and other adventures.
-
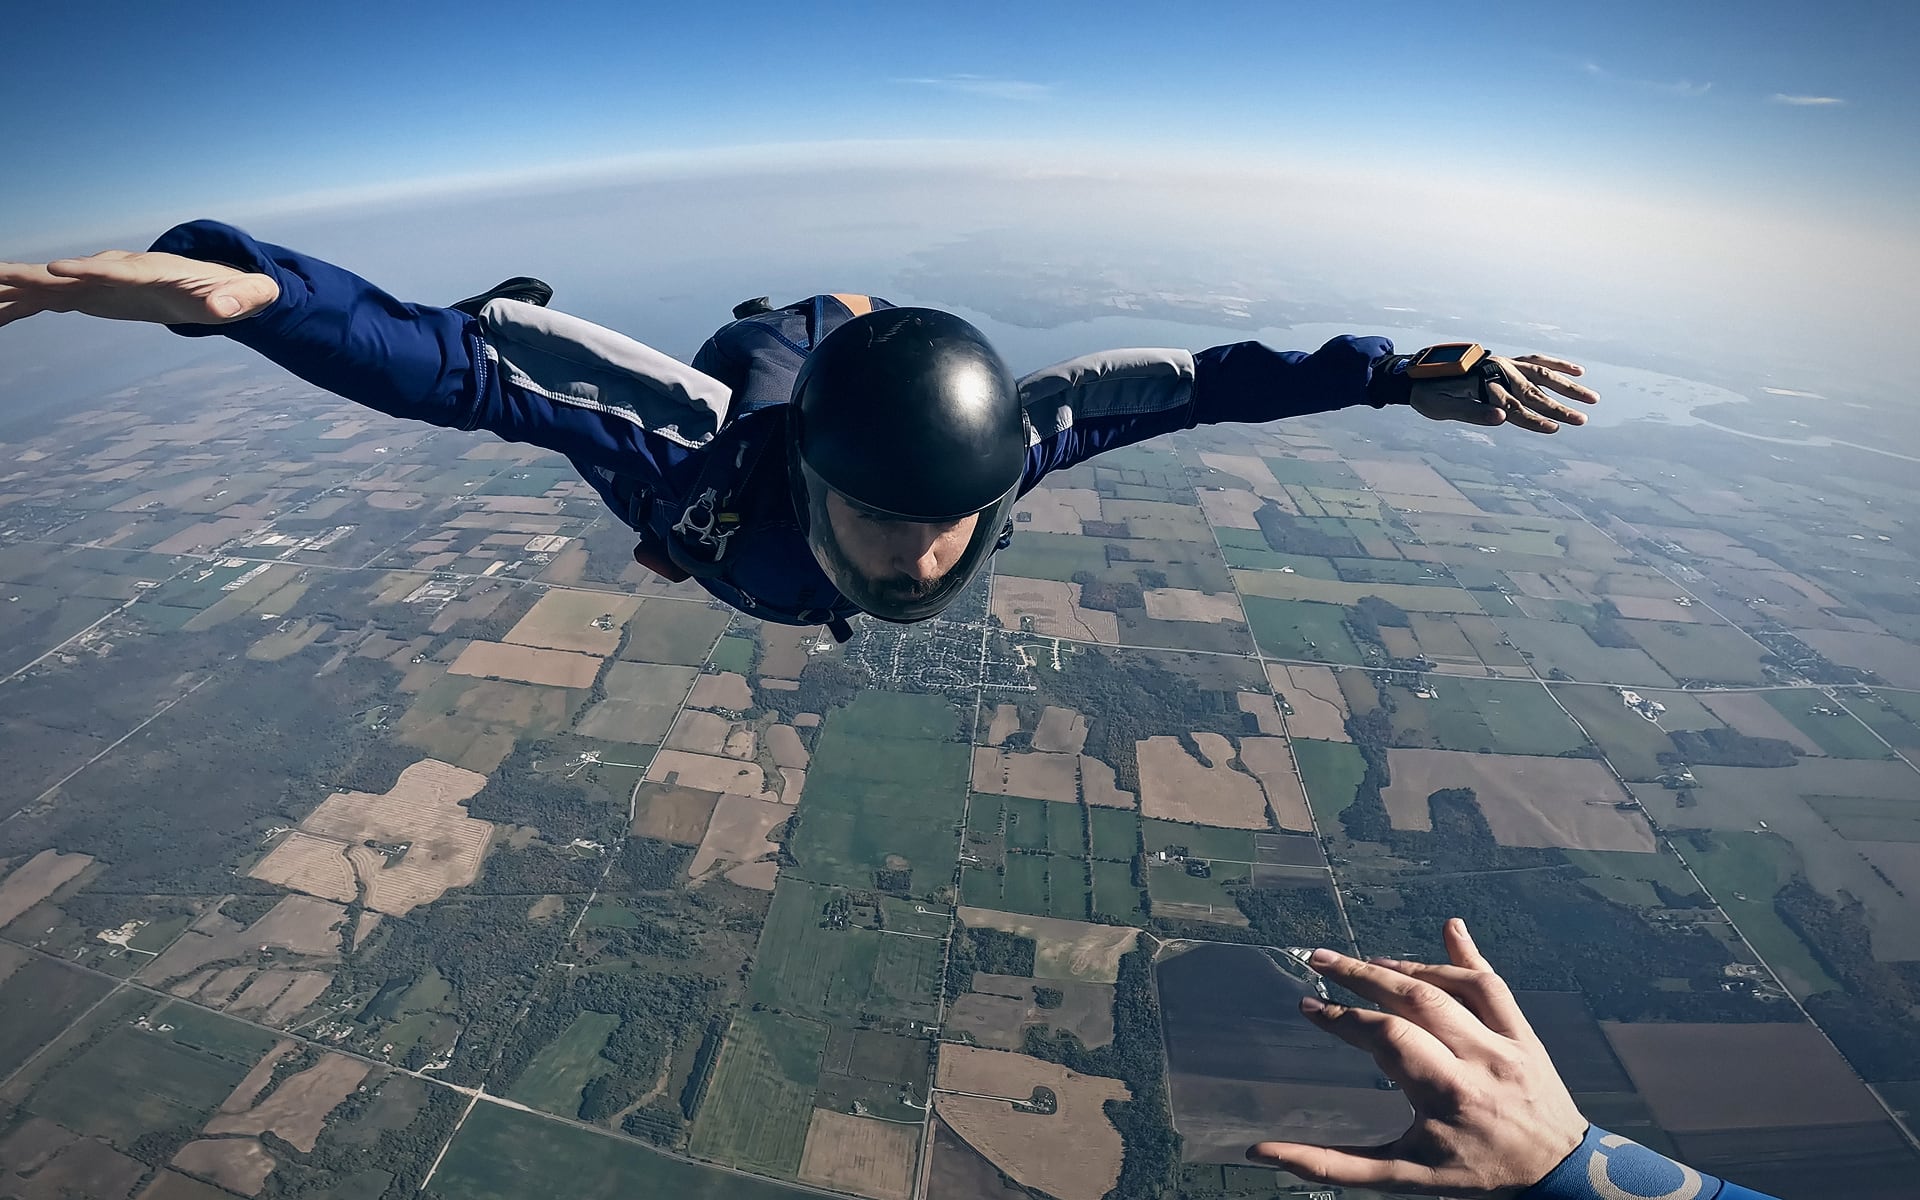
freefall Side slides with a coach Ontario, 2025 -
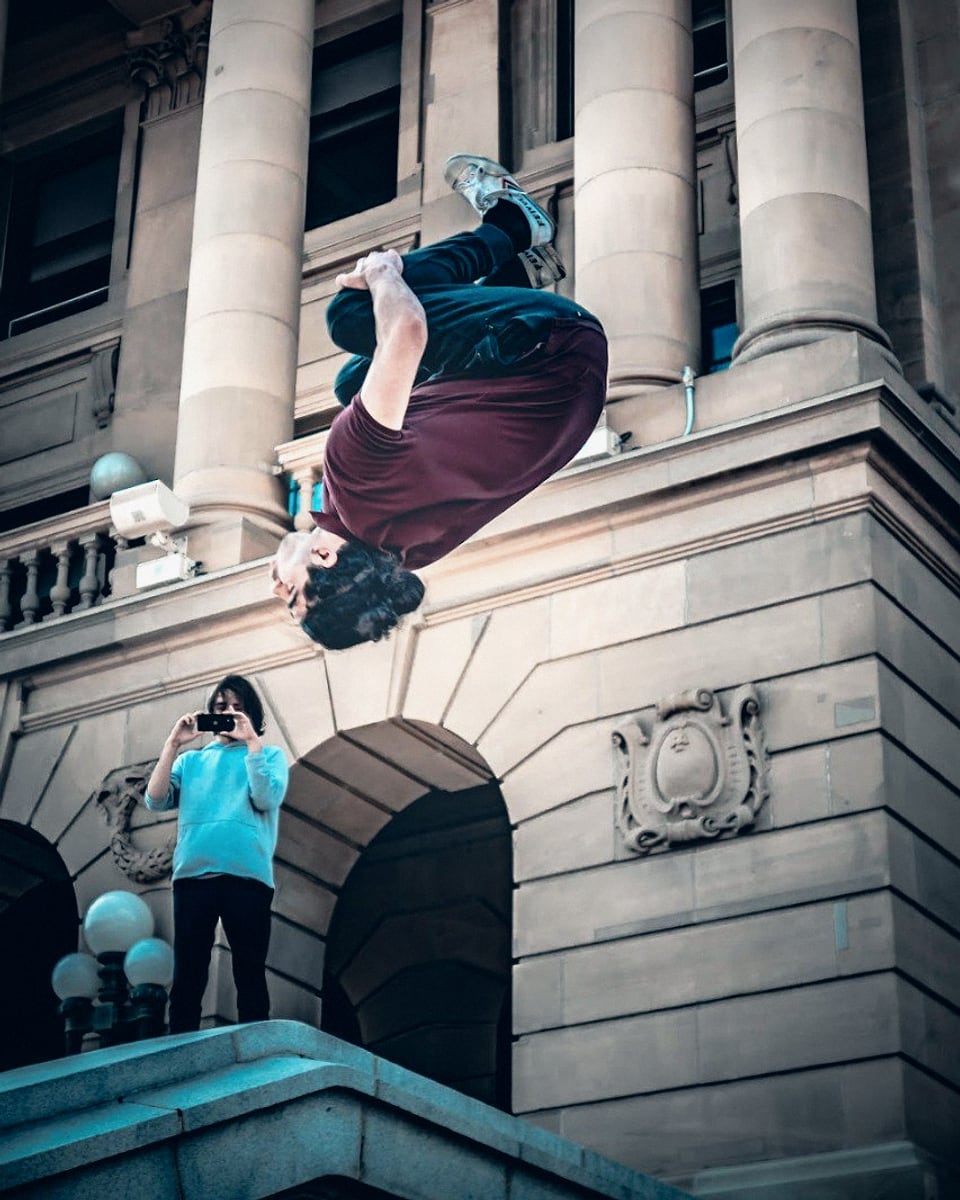
parkour Back tuck at the Alberta Legislature Edmonton -
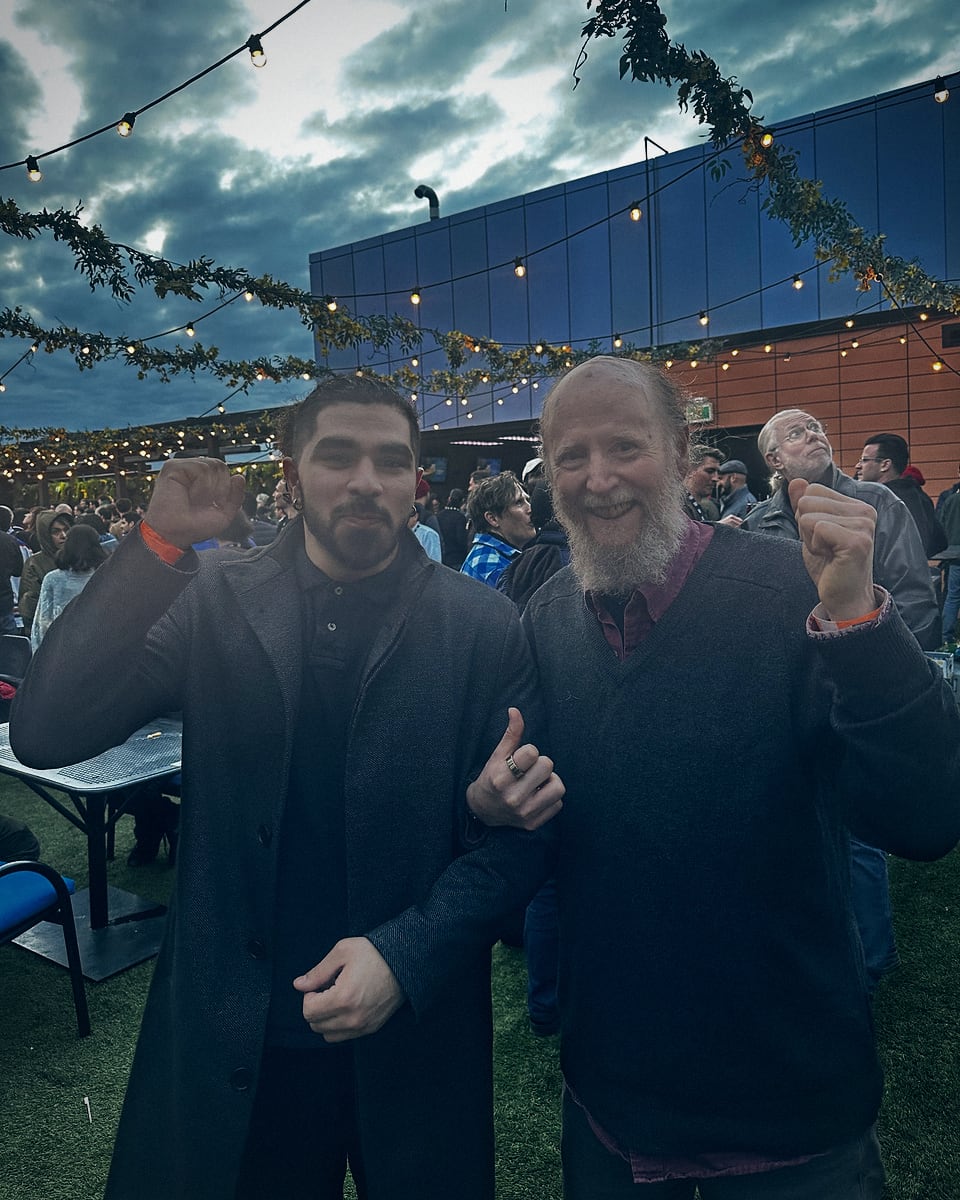
event Fists up with Richard Sutton Edmonton, 2024 -
portrait Under the stairwell skylight 2024 -
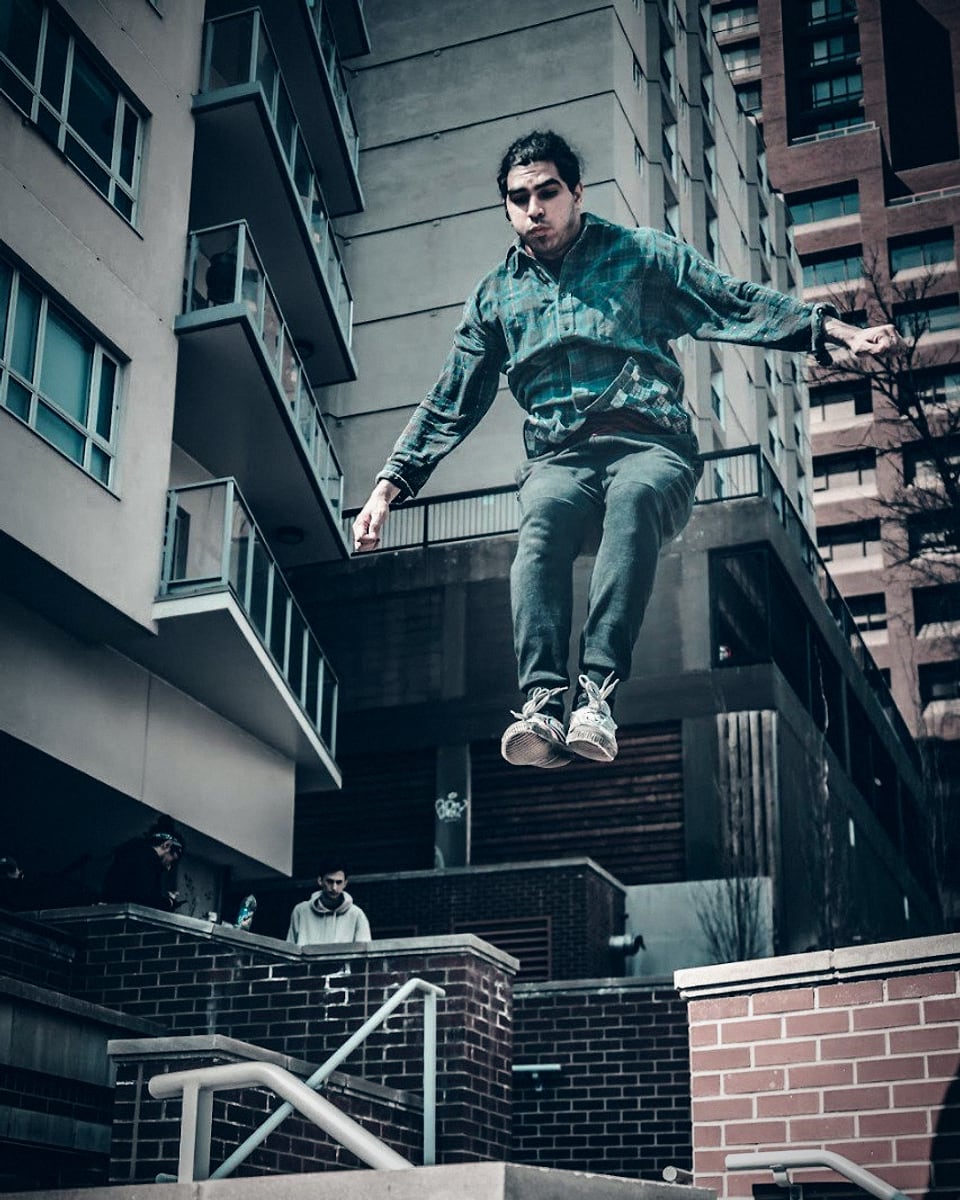
parkour Jump between two brick ledges